A few numbers first
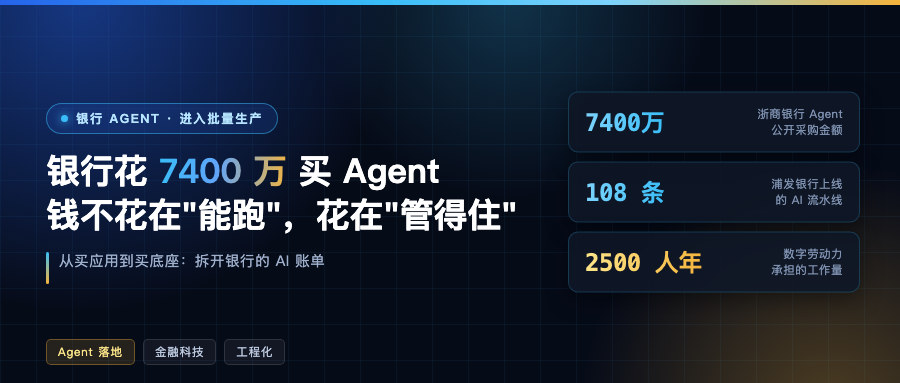
¥65 million — the winning bid on a China Zheshang Bank project for agent base software and hardware. Add the wealth-management and supply-chain agent projects already in production, and Zheshang’s public agent procurement comes to more than ¥74 million in total.
108 — the number of AI pipelines Shanghai Pudong Development Bank put live in the first half. In the same period it shipped 220 engineered agents, with digital labor taking on more than 2,500 person-years of workload.
406 / +110% — large-model contract awards in financial services in the first half of this year, more than double year over year. Banks account for close to half of both the project count and the money.
Put these numbers together and they say one thing:
Banks are moving agent deployment from one-off experiments to more systematic engineering buildout.
What is more worth chewing on is where exactly the money goes.
The money is no longer going to “applications”, it is going to the “foundation”
The usual way people talked about enterprise AI was “buy a solution for one scenario” — build a support agent, build a document-extraction agent, sign off, done.
Look at the recent procurement at these three banks and the direction has changed:
- China Zheshang Bank (the ¥65 million one): covers compute, knowledge engineering, models and the agent runtime — not an application, but “the base environment that supports developing and running agents later”
- Shanghai Pudong Development Bank: bought an agent creation platform, aimed at “creating and managing agents in bulk”
- Hengfeng Bank: built agent observability as its own line item — extending spend to monitoring after go-live
Three checks, three different parts of the production system: one is the underlying runtime, one is the assembly line, one is quality control.
One line in the reporting nails it:
What banks are buying is shifting away from specific applications and continuing toward development and runtime infrastructure.
The industry puts it more bluntly — one fintech has gone as far as defining its agent platform as a “super factory”, with the goal of putting development, deployment, evaluation and management into one system.
Why the shift?
Because once agents go from “a few pilots” to “hundreds running”, the old one-process-per-project approach collapses. Development, evaluation and runtime management have to be standardized — otherwise you have no idea what any of the agents in your hands is doing, or whether any of them deserves more budget.
The genuinely hard part: the process has to be taken apart again
This is the most valuable part of the reporting, and the part most “agent deployment” articles skip.
Not every scenario suits being handed straight to an agent.
A data architect at a joint-stock bank drew a clean line:
Tasks with non-standard input and standard output — intent recognition, extracting contract elements — land easily. But complex flows like credit approval or financial planning need the model embedded in the existing workflow, governed jointly by rules, permissions and human checkpoints.
Note the logic of that split — the more standardized a task is, the easier it is to define right and wrong, the better it suits a machine.
Credit is the textbook case. This year Bank of Suzhou has pushed a whole line: document extraction, due diligence, AI approval, disbursement review, post-loan management. Bank of Shanghai has built out marketing, due diligence and post-loan work for corporate credit.
These projects sit at different stages of a single credit facility, with completely different value density:
Reading materials, extracting data, financial analysis — relatively standard, easier to hand to a machine. The closer you get to risk judgment and the approval step, the heavier the dependence on business experience.
That last clause is where the problem lives: whether a set of financial indicators is anomalous, which questions to keep pushing on, what the same indicators mean at a different point in the industry cycle — there is often no fixed answer. A lot of that judgment is sedimented in a veteran credit officer’s decades of experience.
That kind of “you know it when you see it” experience used to be untransferable to a system.
Some companies are now trying to take it apart. Digital China’s CreditMind reorganizes historical due diligence reports, approval opinions and subsequent loan performance, extracting the logic and experience veteran credit officers use when judging risk, then applies it to new tasks.
The end state looks like this:
Standardized information processing to the machine, extractable experience turned into a Skill, key risk judgments left to a human.
“Turned into a Skill” — anyone who builds AI applications should feel that one.
Not shoving every judgment into the model, but sedimenting the part of the experience that is relatively explicit and can be restated into an invokable skill, while the judgments that genuinely depend on a specific client and long experience stay honestly with people.
Easy to describe, brutally hard to do — it requires business experts to be deeply involved in capturing the knowledge, not the tech department doing it behind a closed door.
The data architect in the piece is blunt about it: business rules, SOPs and experiential judgment have to become logic the model can recognize and execute, and collaboration on both sides has already moved from “delivering requirements” to “developing together and tuning continuously”.
Translation: business experts are no longer the client filing requirements, they are people building the product with you.
What counts as “in production”? SPDB gives three criteria
Zheng Bo, chief AI scientist at Shanghai Pudong Development Bank, boils financial AI reaching production down to three:
It enters a core business process, takes on key tasks previously done by people, and improves customer experience, operating efficiency or risk management.
Those are strict. Hold projects against them and plenty of things billed as “deployed” hit none of the three — not in a core process, doing odd jobs at the edge, and moving no metric.
The first one especially, entering a core business process, is the real watershed. An agent in an edge scenario is a toy. An agent inside a core process is an asset.
On crossing that boundary, the reporting has a more concrete observation:
“AI pipelines” reflect process-level change better than the number of individual agents: different AI capabilities are reorganized in business order, the machine takes a continuous run of tasks, and then the work goes back to a human at the points that need judgment, authorization and accountability.
“Back to a human at the points that need judgment, authorization and accountability” — that line is worth copying down.
It describes what AI deployment actually looks like: not AI taking over wholesale, but one assembly line where people and machines split the work by checkpoint. The machine handles the continuous, standardizable stretch; the human handles the few places that need judgment, a signature, someone to carry the responsibility.
The trouble starts after go-live
Many teams think “signed off” is the finish line. The reporting points at something more real:
An agent passing its tests at launch does not mean its results will stay the same. Business rules, knowledge content and the way customers talk all change, and new counterexamples keep surfacing in real use.
Agents have a shelf life. The model did not change, but the business environment did, so results drift.
And when something does go wrong, attribution is brutal — you have to work out where the problem is:
- Missing knowledge (not enough material fed in)?
- Process design (a hole in the orchestration logic)?
- Or the model not being good enough?
Three causes, three completely different fixes. Traditional software ops only asks “is the system up”. Managing an agent has to ask “are the results still right, is it worth more money, and when it throws, does the process catch it”.
Which is exactly why Hengfeng Bank bought agent observability as a separate line item — not a nice-to-have, a hard requirement.
One signal: the job postings changed
There is a detail in the reporting that looks minor and, I think, matters a lot.
As agent counts grow, banks are posting roles that did not exist before:
- Bank of Ningbo: agent workflow construction, technical framework R&D
- Ping An Bank: AI agent evaluation engineer — tool calling, multi-step reasoning, plus security and performance evaluation
Look at the second one. “Agent evaluation engineer” did not exist two years ago.
What does it tell you? That agents are no longer a “research project” but a production system that needs a dedicated quality role to manage it.
For engineers, this may say more than any industry report — this direction really is hiring and really is spending budget.
Here is a more practical read: banks willing to pay separately for “evaluation” and “observability” means talent in those two links is genuinely scarce right now. Plenty of people can call an API and write an agent. Very few can design an agent evaluation system, or locate the cause when results drift. That gap is the opportunity.
A few of my own takes
After reading this material, a few conclusions I want to share.
First, the real barrier to deploying agents is the ability to take a process apart, not model capability.
The numbers in the reporting (¥65 million, 108 pipelines) show banks are not short on compute or models. What actually stops them is that one question: which tasks go to the machine, which experience can be sedimented into a Skill, which judgments must stay with people.
That partitioning ability is industry knowledge plus engineering ability combined. You cannot buy it, you can only grind it out business line by business line.
Second, the term “AI pipeline” is worth remembering.
It gets closer to the essence than “agent count” — what an enterprise wants is not a pile of agents each fighting its own war, but a production line that strings machine tasks and human checkpoints together.
That also explains why the money flows to “creation platforms” and “observability”: a production line needs a plant and a QA station.
Third, if you build AI applications, do not stare only at “capability”.
Almost none of the hard parts in this reporting are “the model is not smart enough”. They are how knowledge gets captured, how the process gets split, how results get evaluated continuously.
If we only think about plugging in a stronger model when we build AI products, we will very likely get stuck on the actual engineering problems.
Two questions to finish:
At the companies around you, are agents stuck in demo, or have they actually reached a core process?
If you had to build “agent evaluation”, how would you design the standard? (I think this one is genuinely hard, and genuinely interesting.)
Comments are open.